ChatGLM-6B local deployment
Download the project code git clone https://github.com/THUDM/ChatGLM-6B.git Create a virtual environment; conda is recommended for management conda create -n chatglm python==3.8 Install dependencies conda activate chatglm pip install -r requirements.txt conda install cudatoolkit=
Download the project code
git clone https://github.com/THUDM/ChatGLM-6B.git
Create a virtual environment. It is recommended to use conda for management.
conda create -n chatglm python==3.8
Install dependencies
conda activate chatglm
pip install -r requirements.txt
conda install cudatoolkit=11.7 -c nvidia
PS: If
cudatoolkitis not installed, you will encounter the errorRuntimeError: Library cudart is not initialized.However, some users in the issues mention that this can be resolved by using the CPU to output a quantized model and then directly invoking it, though this has not been tried yet.
Issues address: https://github.com/THUDM/ChatGLM-6B/issues/115
Hardware Requirements
| Quantization Level | Minimum GPU Memory (Inference) | Minimum GPU Memory (Efficient Parameter Fine-tuning) |
|---|---|---|
| FP16 (No Quantization) | 13 GB | 14 GB |
| INT8 | 8 GB | 9 GB |
| INT4 | 6 GB | 7 GB |
Modify the startup parameters
model = AutoModel.from_pretrained("THUDM/chatglm-6b", trust_remote_code=True).half().cuda()
Use the quantized model
# Modify as needed, currently only supports 4/8 bit quantization
model = AutoModel.from_pretrained("THUDM/chatglm-6b", trust_remote_code=True).quantize(4).half().cuda()
Download the model and start the Gradio interface
cd ChatGLM-6B
python web_demo.py
Running effect
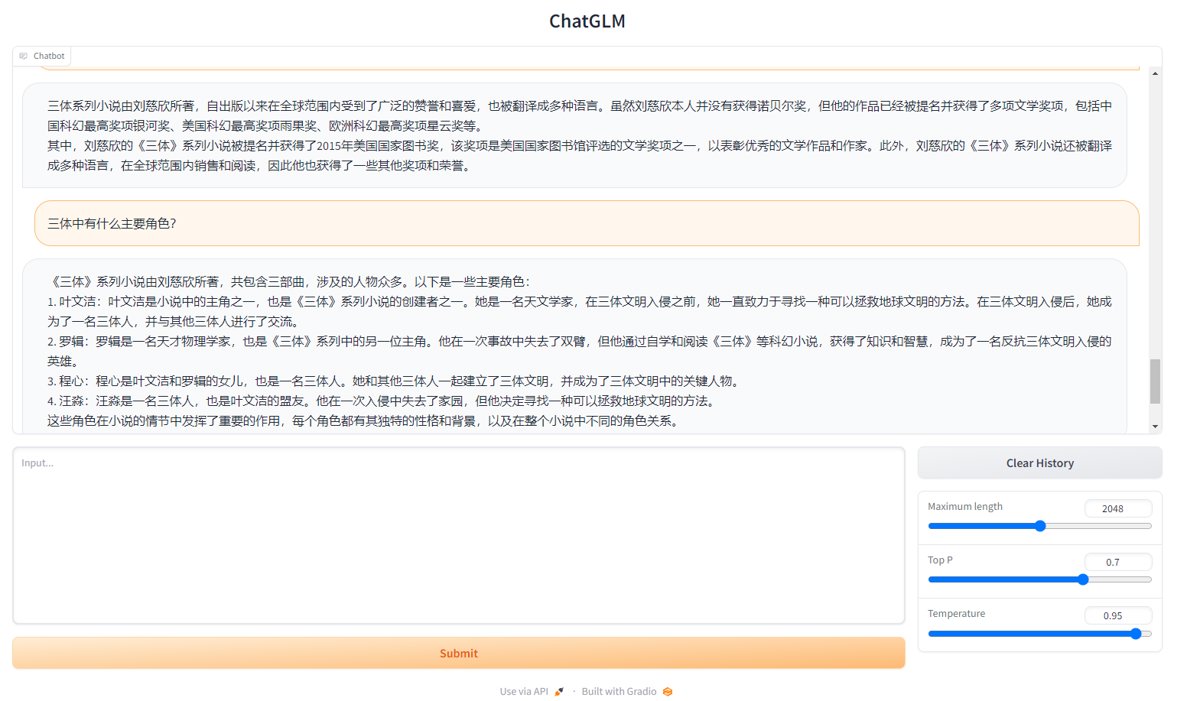
_EOF_
ChatGLM-6B local deployment
- 本文作者:
- 程序设计实验室
- 版权声明:
- 本博客所有文章除特别声明外,均采用 BY-NC-SA 许可协议。转载请注明出处!
相关文章
用本地大模型驱动中文输入法,我做了一个实验性的项目
一个拿350MB小模型给输入法做语境排序的实验,思路倒是比那些堆参数的玩意儿清醒。不过老哥,先用着Web版就别急着吹原生输入法框架,等你能把打字延迟压到100ms以下再说。
2026-05-09 · LLM · 约 1 分钟
本地部署大模型哪个性能好?在 8845HS (780M核显) 上的 LM Studio 基准测试
省流:目前用下来 `google/gemma-4-e4b` 是比较均衡的,在速度和性能方面表现都不错
2026-09-15 · LLM · 约 1 分钟
LLM探索:为ChatGLM2的gRPC后端增加连续对话功能
给ChatGLM2的gRPC后端硬塞了连续对话功能,改了proto、C#客户端和Python服务端代码。OpenAI格式转ChatGLM格式?真够折腾的,幸好有loguru。搞定了,但调试gRPC还是麻烦,考虑改OpenAI接口了。
2026-05-09 · LLM · 约 1 分钟
2GB 显存还能跑大模型吗?我在 MX250 老笔记本上部署 Qwen3.5 2BB
七年前的Matebook14,MX250显存2GB,硬塞Qwen3.5 2B——这届玩家是真的敢。核心思路倒是比模型选择更值得学:先看清楚硬件预算,再决定能跑什么,而不是硬上7B然后等CPU掉帧到怀疑人生。1.81GiB直接顶满2GB显存,KV Cache挤出来的空间里,4K Context刚好够用。至于Agent场景?省省吧,2B让MX250当推理节点做轻量任务已经仁至义尽。
2026-09-15 · LLM · 约 1 分钟
讨论
共 0 条加载评论中…